lilbee MCP工具
lilbee MCP工具 是 AI Skill Hub 本期精选MCP工具之一。综合评分 7.2 分,整体质量较高。我们推荐使用将其纳入你的 AI 工具库,帮助提升工作效率。
📚 深度解析
通过安装 lilbee MCP工具,你的 AI 助手将获得额外的工具调用能力,可以用自然语言直接操控该工具的功能,无需学习复杂的命令行语法。MCP 工具的核心价值在于"一次配置,永久增强"——配置完成后,每次与 AI 对话时都可以无缝调用这些工具。
在技术实现上,MCP 工具通过标准的 JSON-RPC 协议与 AI 客户端通信,工具的功能以"工具列表"的形式暴露给 AI 模型,AI 可以按需调用。lilbee MCP工具 提供了结构化的工具调用接口,使 AI 模型能够精确地理解和使用每个功能点,显著降低 AI 在工具使用上的错误率。
与传统的 API 集成相比,MCP 工具的优势在于无需编写代码——用户只需在配置文件中添加几行 JSON,即可让 AI 获得全新能力。AI Skill Hub 将 lilbee MCP工具 评为 AI 评分 7.2 分,属于同类工具中的优质选择。
📋 工具概览
lilbee MCP工具 是一款遵循 MCP(Model Context Protocol)标准协议的 AI 工具扩展。通过 MCP 协议,它可以让 Claude、Cursor 等主流 AI 客户端直接访问和操作外部工具、数据源和服务,实现 AI 能力的无缝扩展。无论是文件操作、数据库查询还是 API 调用,都可以通过自然语言在 AI 对话中直接触发,极大提升生产效率。
📖 中文文档
lilbee MCP工具 是一款遵循 MCP(Model Context Protocol)标准协议的 AI 工具扩展。通过 MCP 协议,它可以让 Claude、Cursor 等主流 AI 客户端直接访问和操作外部工具、数据源和服务,实现 AI 能力的无缝扩展。无论是文件操作、数据库查询还是 API 调用,都可以通过自然语言在 AI 对话中直接触发,极大提升生产效率。
- 通过标准 MCP 协议与 Claude、Cursor 等主流 AI 客户端深度集成
- 提供结构化工具调用接口,显著降低 AI 集成复杂度
- 支持 Claude Desktop 和 Claude Code 无缝接入,开箱即用
- 可与其他 MCP 工具组合叠加,构建完整 AI 工作站
- 轻量无侵入设计,不影响现有系统架构
- 在 Claude Desktop 对话中直接调用本地工具,实现 AI 与系统的深度联动
- 通过自然语言驱动复杂的多步骤自动化任务,代替繁琐手动操作
- 将多个 MCP 工具组合使用,构建个人专属 AI 工作站
# 方式一:通过 Claude Code CLI 一键安装
claude skill install https://github.com/tobocop2/lilbee

# 方式二:手动配置 claude_desktop_config.json
{
  "mcpServers": {
    "lilbee-mcp--": {
      "command": "npx",
      "args": ["-y", "lilbee"]
    }
  }
}

# 配置文件位置
# macOS: ~/Library/Application Support/Claude/claude_desktop_config.json
# Windows: %APPDATA%/Claude/claude_desktop_config.json
- 确认已安装 Node.js(v18 或以上版本)
- 打开 Claude Desktop 或 Claude Code 的 MCP 配置文件
- 按「交给 Agent 安装 → Claude Desktop」标签中的 JSON 配置填入 mcpServers 字段
- 保存配置文件并重启 Claude 客户端
- 重启后,在对话中即可使用本工具
# 安装后在 Claude 对话中直接使用
# 示例:
用户: 请帮我用 lilbee MCP工具 执行以下任务...
Claude: [自动调用 lilbee MCP工具 MCP 工具处理请求]

# 查看可用工具列表
# 在 Claude 中输入:"列出所有可用的 MCP 工具"
// claude_desktop_config.json 配置示例
{
  "mcpServers": {
    "lilbee_mcp__": {
      "command": "npx",
      "args": ["-y", "lilbee"],
      "env": {
        // "API_KEY": "your-api-key-here"
      }
    }
  }
}

// 保存后重启 Claude Desktop 生效
简介
<p align="center"> <a href="https://lilbee.sh/"> <picture> <source media="(prefers-color-scheme: dark)" srcset="https://raw.githubusercontent.com/tobocop2/lilbee/main/docs/lilbee-logo-dark.svg"> <img alt="lilbee" src="https://raw.githubusercontent.com/tobocop2/lilbee/main/docs/lilbee-logo-light.svg" width="340"> </picture> </a> </p>
<p align="center"><strong>The whole local AI stack in one executable: it runs and manages the models, and searches everything you own with them.</strong></p>
<p align="center"><a href="https://lilbee.sh/">Project site</a> · <a href="https://lilbee.sh/tutorial">Tutorial reels</a> · <a href="https://pypi.org/project/lilbee/">PyPI</a> · <a href="https://obsidian.lilbee.sh/">Obsidian plugin</a> · <a href="https://lilbee.sh/api/">REST API</a> · <a href="https://web.libera.chat/#lilbee">Chat (#lilbee)</a></p>
<p align="center"> <a href="https://github.com/tobocop2/lilbee/releases/latest"><img src="https://img.shields.io/github/v/release/tobocop2/lilbee?label=release&logo=github&logoColor=c4a7e7&style=flat-square&labelColor=191724&color=c4a7e7" alt="Latest release"></a> <a href="https://pypi.org/project/lilbee/"><img src="https://img.shields.io/pypi/v/lilbee?include_prereleases&label=PyPI&logo=pypi&logoColor=9ccfd8&style=flat-square&labelColor=191724&color=9ccfd8" alt="lilbee on PyPI"></a> <a href="https://www.python.org/downloads/"><img src="https://img.shields.io/badge/python-3.11%2B-9ccfd8?logo=python&logoColor=9ccfd8&style=flat-square&labelColor=191724" alt="Python 3.11+"></a> <a href="LICENSE"><img src="https://img.shields.io/badge/license-MIT-6e6a86?style=flat-square&labelColor=191724" alt="License: MIT"></a> <a href="https://github.com/tobocop2/lilbee/actions/workflows/ci.yml"><img src="https://img.shields.io/github/actions/workflow/status/tobocop2/lilbee/ci.yml?branch=main&label=CI&logo=githubactions&logoColor=9ccfd8&style=flat-square&labelColor=191724&color=9ccfd8" alt="CI"></a> <a href="https://lilbee.sh/coverage/"><img src="https://img.shields.io/badge/coverage-100%25-31748f?style=flat-square&labelColor=191724" alt="Coverage"></a> <a href="https://mypy-lang.org/"><img src="https://img.shields.io/badge/typed-mypy-c4a7e7?style=flat-square&labelColor=191724" alt="Typed"></a> <a href="https://github.com/astral-sh/ruff"><img src="https://img.shields.io/endpoint?url=https://raw.githubusercontent.com/astral-sh/ruff/main/assets/badge/v2.json&style=flat-square" alt="Ruff"></a> </p>
<p align="center"> <img src="https://img.shields.io/badge/platform-macOS%20%7C%20Linux%20%7C%20Windows-908caa?style=flat-square&labelColor=191724" alt="Platforms"> <a href="https://github.com/tobocop2/homebrew-lilbee"><img src="https://img.shields.io/badge/Homebrew-tap-f6c177?logo=homebrew&logoColor=f6c177&style=flat-square&labelColor=191724" alt="Homebrew tap"></a> <a href="https://aur.archlinux.org/packages/lilbee"><img src="https://img.shields.io/badge/AUR-package-c4a7e7?logo=archlinux&logoColor=c4a7e7&style=flat-square&labelColor=191724" alt="lilbee on the AUR"></a> <a href="https://github.com/tobocop2/lilbee#install"><img src="https://img.shields.io/badge/Nix-flake-c4a7e7?logo=nixos&logoColor=c4a7e7&style=flat-square&labelColor=191724" alt="Nix flake"></a> <a href="https://github.com/tobocop2/scoop-lilbee"><img src="https://img.shields.io/badge/Scoop-bucket-908caa?logo=windows&logoColor=908caa&style=flat-square&labelColor=191724" alt="Scoop bucket"></a> <a href="https://github.com/tobocop2/lilbee/pkgs/container/lilbee"><img src="https://img.shields.io/badge/Docker-ghcr.io-9ccfd8?logo=docker&logoColor=9ccfd8&style=flat-square&labelColor=191724" alt="Docker image on GHCR"></a> <a href="https://github.com/tobocop2/flatpak-lilbee"><img src="https://img.shields.io/badge/Flatpak-repo-9ccfd8?logo=flatpak&logoColor=9ccfd8&style=flat-square&labelColor=191724" alt="Flatpak repo"></a> <a href="https://github.com/tobocop2/lilbee/releases/latest"><img src="https://img.shields.io/badge/Snap-sideload-f6c177?logo=snapcraft&logoColor=f6c177&style=flat-square&labelColor=191724" alt="Snap package"></a> <a href="https://pypi.org/project/lilbee/"><img src="https://img.shields.io/badge/PyPI-pip%20%7C%20uv-9ccfd8?logo=pypi&logoColor=9ccfd8&style=flat-square&labelColor=191724" alt="Install from PyPI"></a> <a href="https://www.npmjs.com/package/lilbee"><img src="https://img.shields.io/npm/v/lilbee?label=npm&logo=npm&logoColor=ebbcba&style=flat-square&labelColor=191724&color=ebbcba" alt="lilbee on npm"></a> </p>
<p align="center"> <a href="https://github.com/tobocop2/lilbee/releases"><img src="https://img.shields.io/github/downloads/tobocop2/lilbee/total?label=downloads&logo=github&logoColor=9ccfd8&style=flat-square&labelColor=191724&color=9ccfd8" alt="Release downloads"></a> <a href="https://glama.ai/mcp/servers/tobocop2/lilbee"><img src="https://glama.ai/mcp/servers/tobocop2/lilbee/badges/score.svg" alt="Glama MCP server score"></a> <a href="https://mcptoplist.com/server/glama%2Ftobocop2%2Flilbee"><img src="https://img.shields.io/badge/dynamic/regex?url=https%3A%2F%2Fmcptoplist.com%2Fbadge%2Fglama%252Ftobocop2%252Flilbee.svg&search=Top%20(%5B0-9%5D%2B%25%20of%20%5B0-9,%5D%2B)&replace=Top%20%241&label=MCP%20Toplist&labelColor=191724&color=ebbcba&style=flat-square" alt="MCP Toplist rank"></a> </p>
<p align="center"> <a href="https://community.obsidian.md/plugins/lilbee"><img src="https://img.shields.io/badge/Obsidian-Community%20plugin-c4a7e7?logo=obsidian&logoColor=c4a7e7&style=flat-square&labelColor=191724" alt="Obsidian community plugin"></a> <a href="https://web.libera.chat/#lilbee"><img src="https://img.shields.io/badge/IRC-%23lilbee%20on%20Libera.Chat-f6c177?logo=liberadotchat&logoColor=f6c177&style=flat-square&labelColor=191724" alt="#lilbee on Libera.Chat"></a> </p>
lilbee runs and manages your models: chat, embedding, vision, and rerank, placed across every GPU you have. It puts them to work as a search engine you can talk to, over your files, notes, code, and the web, where every answer cites the exact file and line. It crawls websites into your library, launches your coding agents on local models, and hands any MCP-aware agent cited answers from everything you've indexed. The same engine backs the Obsidian community plugin, so your vault gets all of it without a terminal. Ask in plain English. No containers, no networking, nothing else to install or set up.
And it is private. Your files, the index, the embeddings, your questions, and the answers stay on your machine. lilbee sends no telemetry and needs no account. It contacts a cloud provider only when you set an API key for it, in lilbee's settings or in the provider's own environment variable. Then it checks once that the key works, and sends your questions only to a cloud model you pick.
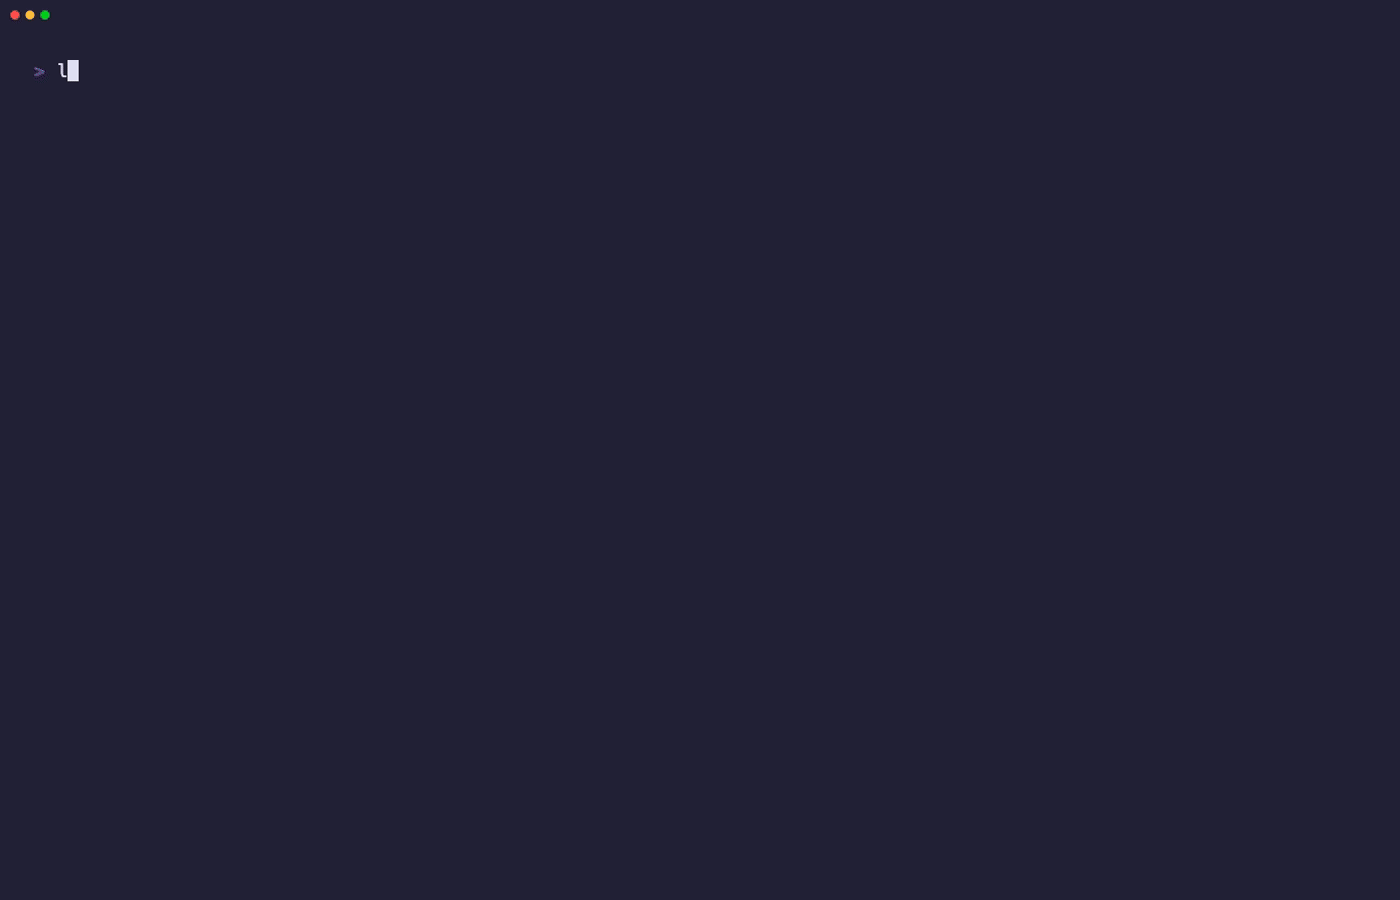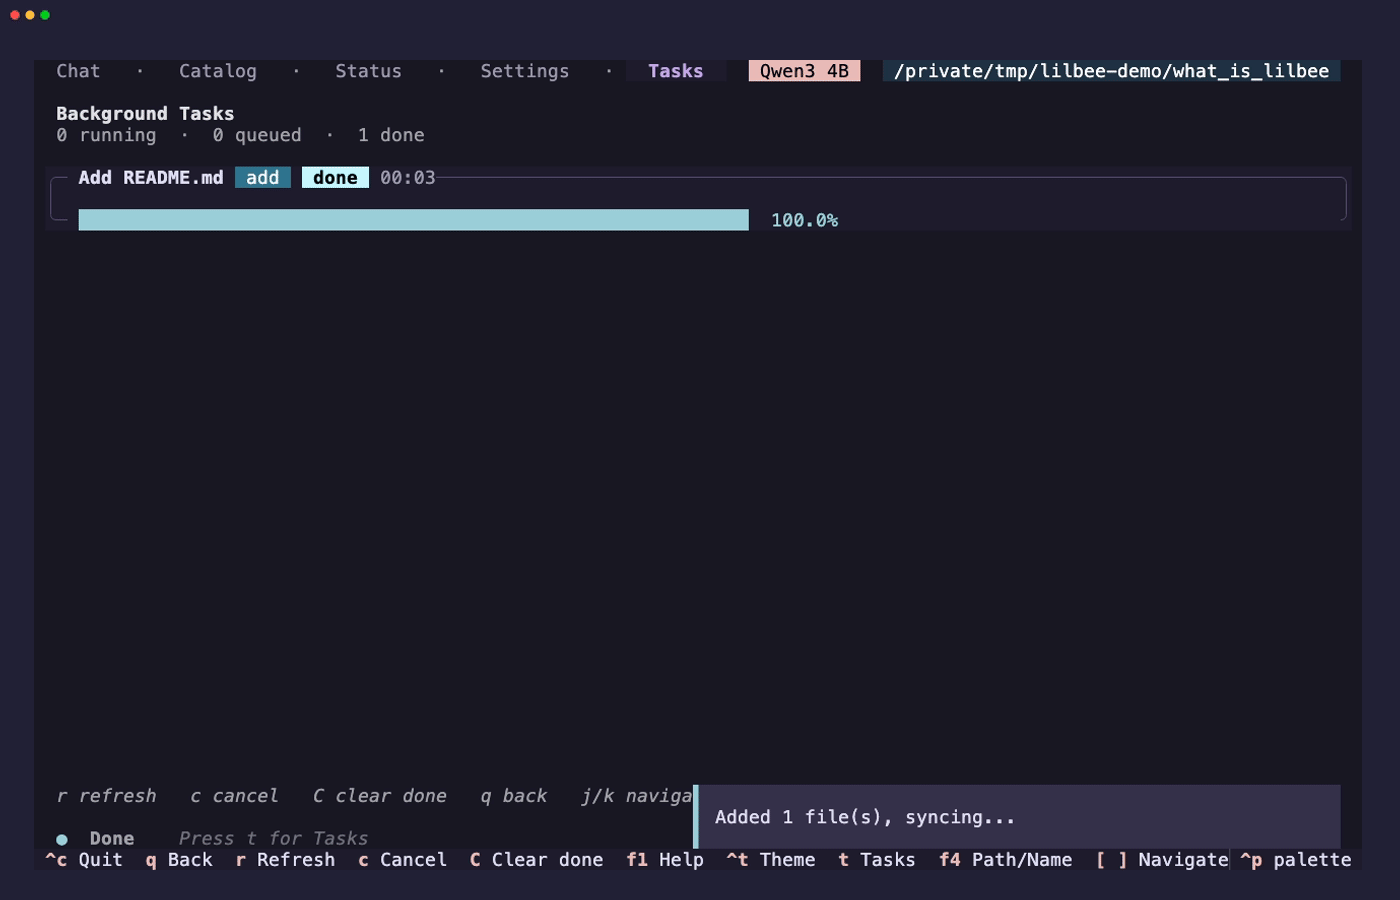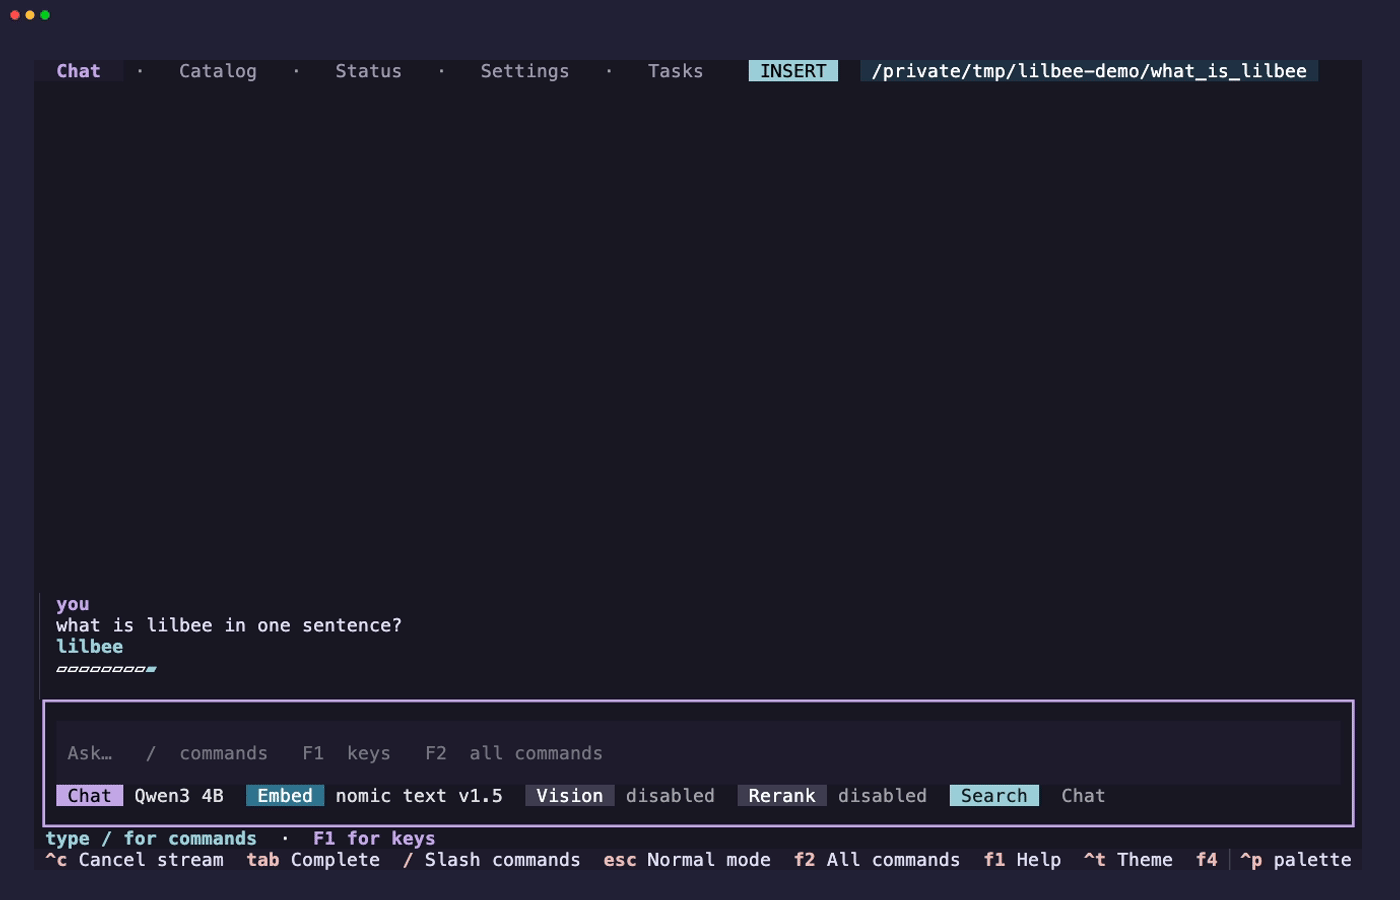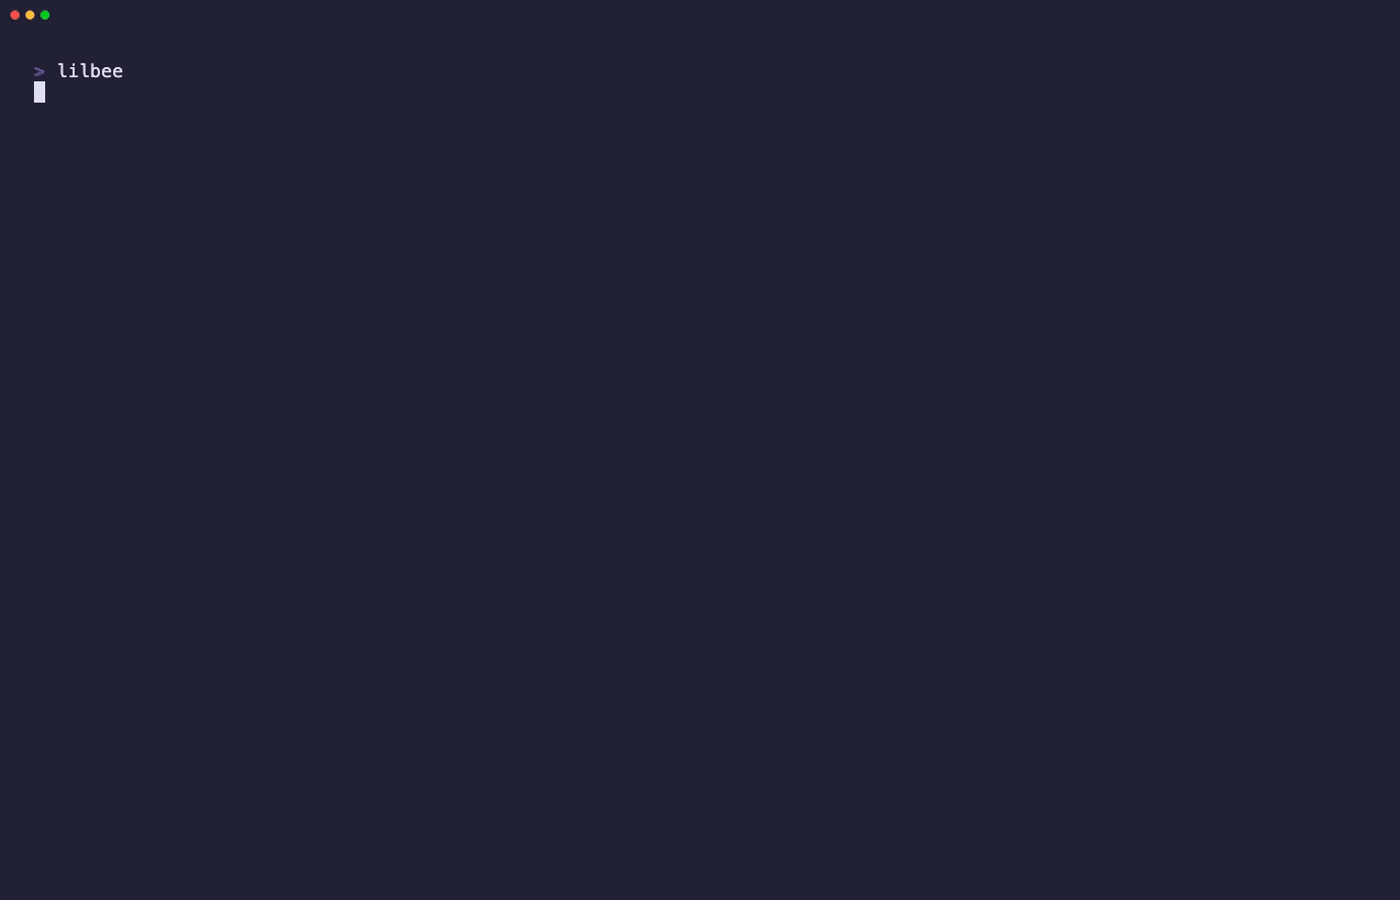
It's all one program: no separate model server, vector database, or container to stand up. lilbee runs the models and keeps the index itself. Reach it as a terminal app, CLI, Model Context Protocol server, HTTP API, or Python library. Close it and it's gone, or run it as a service to keep it warm. Everything runs on your computer; it uses a cloud model only when you pick one.
Models are no different: lilbee has its own model manager and multi-GPU fleet, built on llama.cpp, so one executable does everything (browse Hugging Face, download a model, give it a role, run it on Metal / Vulkan / CUDA). You don't need Ollama or LM Studio at all: the architectures lilbee runs are behind most of the 190,000+ GGUF repos on Hugging Face, with representatives verified on real GPUs. If you already use them, point lilbee at your existing setup and keep your models.
Tutorial reel: every demo on this page, plus the extras that don't fit here, with long-form captions at lilbee.sh/tutorial.
## ⚠️ Beta software lilbee is in active beta development. Every release on PyPI is a pre-release; you must use--pre(or uv's--prerelease=allow) when installing. Interfaces, command names, and on-disk formats may shift between betas. Feedback, bug reports, and issues are very welcome; that's the whole point of the beta. Latest pre-release (always): lilbee on PyPI →
---
- Quick start
- Tutorial reel (long-form videos)
- Install
- Hardware requirements
- Highlights
- Why lilbee
- First start
- What you can do with it
- Agents
- TUI
- HTTP Server · REST API reference
- Supported formats
- Wiki
- Built on
---
Highlights
- Private by default. The models, the index, and every question and answer stay on your machine. No telemetry, no account. lilbee contacts a cloud provider only when you set its API key: once to check the key, then only for a cloud model you pick.
- Answers cite the source line. Click a citation, jump to the file at the exact line; when the answer isn't in your library, lilbee says so instead of inventing one.
- It works, and the demos prove it. Every GIF and reel here is recorded live on real hardware, nothing staged, backed by 100% test coverage, full typing, and CI on macOS, Linux, and Windows.
- One command to running. Install, run
lilbee, pick a model that fits your machine from the catalog, and you're chatting. - Reads almost anything: 90+ formats and 150+ languages across documents, scanned pages, spreadsheets, ebooks, web pages, and source code.
- Chunks that stand on their own. Prose and code are split differently so each piece keeps its meaning, which is where most of the retrieval quality lives.
- A real search engine on top, ranking every result by how well it answers you, with 50+ tunable knobs and sane defaults.
- It brings and runs the models itself, on Metal, Vulkan, or CUDA, with no server to point at and no cloud account. Browse Hugging Face, pull a model, give it a role (chat, embedding, vision, rerank).
- A model too big for one card runs across all of them, sized with gguf-parser and tensor-split automatically, or pinned by hand. Run a model bigger than one card.
- Already on Ollama or LM Studio? Keep them. lilbee's own manager covers the same architectures they run, and their models also show up in the same pickers.
- One install, many surfaces: TUI, CLI, MCP server, REST API, and Python library, so your coding agent answers from your real files, with citations.
- Everything in one file, nothing to operate. The binary bundles the whole stack (search engine, crawler, MCP + HTTP servers, TUI, Python, llama.cpp) in ~360-530 MB, or ~0.7-1.3 GB with CUDA; it loads on demand and nothing stays running.
- Per-project libraries. One library for everything, or one per project.
Linux runtime requirements
The Linux x86_64 wheel and binary bundle the Vulkan loader, so they start on any distro. GPU detection still reads adapters through the system loader, though: without libvulkan1 lilbee treats the machine as CPU-only. Most desktop distros (Ubuntu 22.04+, Pop!\_OS, Mint) ship it; on bare Arch / Fedora / Alpine images install it once: sudo pacman -S vulkan-icd-loader (Arch / Manjaro), sudo dnf install vulkan-loader (Fedora, RHEL), or sudo apt-get install libvulkan1 (Debian, Ubuntu).
Hardware requirements
Standalone mode needs nothing but your machine. No cloud required. Minimum: Apple Silicon Mac, or a 64-bit Intel/AMD CPU from 2013+ (older CPUs: On older CPUs), or an ARMv8 Linux box; 8 GB RAM, 2 GB disk.
<details> <summary>Full platform and resource breakdown</summary>
| Platform | Minimum | Recommended |
|---|---|---|
| **macOS arm64** | Apple Silicon (M1 or newer), macOS 11+ | M-series Pro / Max / Ultra |
| **macOS x86_64** | Intel Mac with AVX (Ivy Bridge or newer), macOS 12+ | Quad-core Intel with 16+ GB RAM |
| **Linux x86_64** | 64-bit Intel/AMD from 2013+ ([x86-64-v3](https://en.wikipedia.org/wiki/X86-64#Microarchitecture_levels)) | Modern Intel/AMD CPU + an NVIDIA, AMD, or Intel Arc GPU |
| **Windows x86_64** | 64-bit Intel/AMD from 2013+ (x86-64-v3), Windows 10/11 | Modern desktop / workstation CPU + GPU |
| **Linux ARM64** | ARMv8 NEON-capable (Raspberry Pi 4+, AWS Graviton, Ampere Altra) | Modern ARM server with 16+ GB RAM |
| Resource | Minimum | Recommended |
|---|---|---|
| **RAM** | 8 GB | 16 to 32 GB to keep several local models warm at once (chat + embed + rerank + vision); actual footprint scales with the sizes and quantizations you pick |
| **GPU / Accelerator** | none required (CPU-only works) | Apple Silicon (Metal) · NVIDIA / AMD / Intel Arc (Vulkan) · faster vendor builds with the runtime bundled: CUDA on NVIDIA, ROCm on AMD (see [Install](#install)) |
| **Disk** | 2 GB | 10+ GB for multiple models |
</details>
Install
Two routes, and the difference matters:
- A self-contained bundle (start here): the standalone binary, or the Homebrew / AUR / Nix / Docker / Flatpak / Snap / Scoop builds that wrap it. It carries its own Python runtime,
llama.cpp, the model engine, and the optional extras, so there is nothing else to install and nothing to assemble. The trade-off is one large download and a small cold-start cost the first time it self-extracts. - Into your own Python with
piporuv(Python 3.11 to 3.14), in its own section below. This is the developer route: it installs lilbee as a library in an environment you manage, and the model engine is a separate extra from a separate index that you have to ask for. Take it if you are working on lilbee or importing it into your own code.
Have a discrete GPU? The bundled builds and the Vulkan engine already use it. There are faster vendor builds too: NVIDIA (CUDA) and AMD (ROCm).
No external services either way; lilbee downloads and runs models locally. Optional, for scanned-PDF / image OCR: Tesseract (brew install tesseract / apt install tesseract-ocr) or a GGUF vision model.
| How | Command | Notes |
|---|---|---|
| **Homebrew** | brew tap tobocop2/lilbee && brew install lilbee | macOS (Apple silicon and Intel) / Linux x86_64. Bundled build; clears the macOS quarantine flag for you. |
| **AUR** | paru -S lilbee | Arch Linux. Wraps the Linux x86_64 binary; works with yay / pacaur / any helper. |
| **Docker** | docker run --rm -v lilbee-data:/home/lilbee/data ghcr.io/tobocop2/lilbee:latest --help | GHCR image, tagged by version and latest. Data lives at /home/lilbee/data. Mount a volume there. :cuda and :rocm tags carry the vendor builds. |
| **Nix** | nix run github:tobocop2/lilbee | NixOS, nix-darwin, or any host with nix. On Linux the flake bundles glibc, libgomp, and vulkan-loader so it runs on bare NixOS. |
| **Flatpak** | flatpak remote-add --if-not-exists lilbee https://tobocop2.github.io/flatpak-lilbee/lilbee.flatpakrepo && flatpak install lilbee io.github.tobocop2.lilbee | Linux x86_64, any distro with flatpak. Needs the [Flathub remote](https://flathub.org/setup) for the runtime. Run with flatpak run io.github.tobocop2.lilbee, or make it a plain command: alias lilbee='flatpak run io.github.tobocop2.lilbee' in your shell rc (swap in .cuda / .rocm / .compat for a vendor build). flatpak update picks up new releases. Data lives under ~/.var/app/io.github.tobocop2.lilbee/. Prefer one file? Grab lilbee.flatpakref from the [release](https://github.com/tobocop2/lilbee/releases/latest) and flatpak install ./lilbee.flatpakref. |
| **Snap** | curl -LO https://github.com/tobocop2/lilbee/releases/latest/download/lilbee-linux-x86_64.snap && sudo snap install ./lilbee-linux-x86_64.snap --dangerous --classic | Linux x86_64. Sideloaded, so snapd flags it --dangerous (it just means unsigned) and it won't auto-update; rerun the same command to upgrade. |
| **Scoop** | scoop install git; scoop bucket add lilbee https://github.com/tobocop2/scoop-lilbee; scoop install lilbee | Windows x86_64. Scoop needs git to add a bucket, so the first command installs it (a no-op when present). Reads your NVIDIA driver version and installs the matching CUDA build (555.85+ gets cu125, 551.61+ gets cu124), otherwise the Vulkan build. It says which one it picked. scoop update lilbee upgrades. Added the bucket before 2026-09-08? It moved to its own repository, so run scoop bucket rm lilbee and add it again; your install is untouched. |
| **npm** | npm install -g lilbee | macOS / Linux x86_64 / Windows, Node 18+. A small launcher: on first run it detects your hardware (CUDA, ROCm, Metal, or the AVX-baseline build), downloads the matching standalone binary of the latest release, verifies it, and caches it. lilbee prepare does that ahead of time; npx -y lilbee mcp runs the MCP server for agent hosts. |
| **Standalone binary** | [download for your platform →](https://github.com/tobocop2/lilbee/releases/latest) | One file, own Python runtime, no pip needed. Linux needs glibc 2.28+; the macOS / Windows builds are unsigned (xattr -d com.apple.quarantine ./lilbee-macos-arm64 if Gatekeeper blocks it). |
Developer install: pip and uv
For working on lilbee, or importing it as a library into an environment you manage. Everything below needs the [engine] extra and its index; the bundled builds above do not.
<details> <summary><strong>pip / uv install commands, and the engine index per hardware</strong></summary>
| How | Command | Notes |
|---|---|---|
| **pip** | pip install --pre 'lilbee[engine]' --extra-index-url https://lilbee.sh/cpu/ | Python 3.11 to 3.14. Runs on any x86_64 CPU with AVX2 (2013+; older CPUs: [On older CPUs](#on-older-cpus-pre-avx2)). Swap the index for your hardware, below. |
| **uv** | uv tool install --prerelease=allow 'lilbee[engine]' --extra-index-url https://lilbee.sh/cpu/ | Same wheels as pip; fetches a Python for you if you need one. |
| **From source** | git clone https://github.com/tobocop2/lilbee && cd lilbee && uv sync && uv run lilbee | Needs git and uv. uv sync resolves the in-repo engine package, but CI is what fills its bin/, so a checkout has no engine binaries: install the [engine] extra from the index below, or point LILBEE_LLAMA_SERVER_PATH at your own llama-server. |
The engine. llama-server runs every model, and it ships as the [engine] extra rather than as part of lilbee. It is not on PyPI: the CUDA and ROCm wheels run 444 MiB to 863 MiB each, several times PyPI's default 100 MiB per-file limit, so every backend is published from lilbee's own PEP 503 package index at lilbee.sh. That is what --extra-index-url is for, and the index you pick is the build you get: cpu is compiled with every GPU backend off, metal publishes only a macOS arm64 wheel, vulkan only Linux and Windows ones.
| Hardware | Index | Command |
|---|---|---|
| **NVIDIA (CUDA)** | cu125 | pip install --pre 'lilbee[engine]' --extra-index-url https://lilbee.sh/cu125/ |
| **AMD (ROCm)** | rocm | pip install --pre 'lilbee[engine]' --extra-index-url https://lilbee.sh/rocm/ |
| **Apple silicon** | metal | pip install --pre 'lilbee[engine]' --extra-index-url https://lilbee.sh/metal/ |
| **Other GPUs** | vulkan | pip install --pre 'lilbee[engine]' --extra-index-url https://lilbee.sh/vulkan/ |
| **No GPU** | cpu | pip install --pre 'lilbee[engine]' --extra-index-url https://lilbee.sh/cpu/ |
Leave the extra off and lilbee still installs and starts. The first thing that needs a model then fails with an error naming the engine and repeating the command for your hardware, so it is recoverable rather than mysterious, but it is a step you have to take.
</details>
Install size (single-file download, models excluded)
Download sizes in decimal GB/MB (bytes ÷ 1000), measured from each project's own release artifacts, linked. lilbee and Ollama measured 2026-07-25 from their release APIs (lilbee v0.6.90b420.dev726, Ollama v0.32.4).
| macOS | Windows | Linux | What you get | |
|---|---|---|---|---|
| **[lilbee](https://github.com/tobocop2/lilbee/releases)** (Metal / Vulkan, default) | 317 MB | 333 MB | 478 MB | the whole stack: search engine, crawler, servers, TUI, model runner, fleet manager |
| **[lilbee](https://github.com/tobocop2/lilbee/releases)** (CUDA, opt-in for NVIDIA) | n/a | 666 MB | 1.25 GB | the same whole stack, with the faster CUDA runtime |
| **[lilbee](https://github.com/tobocop2/lilbee/releases)** (ROCm, opt-in for AMD) | n/a | n/a | 854 MB* | the same whole stack, with the faster ROCm runtime |
| [Ollama](https://github.com/ollama/ollama/releases) | 181 MB | 1.56 GB (CUDA bundled) | 1.42 GB (CUDA bundled) | a model runner, fetches its runtimes separately |
| [LM Studio](https://lmstudio.ai/download) | 569 MB | 617 MB | 1.10 GB | a desktop app (Electron) |
| [vLLM](https://docs.vllm.ai/en/stable/getting_started/installation/gpu/) | n/a | n/a | multi-GB | a Python + CUDA serving engine |
Even lilbee's CUDA build stays under Ollama's, and it's the whole stack, not just a model runner.
\* ROCm is the one figure not yet from a release: it is the binary CI builds today, measured, and lands here unchanged at the first release that carries it.
</details>
Already on Ollama or LM Studio? lilbee runs on top of them. Prefer a GUI to the terminal? The Obsidian plugin maps lilbee's model manager and search to a visual interface inside your vault.
Quick start
Two recommended ways to use lilbee, depending on whether you're the one driving:
- Run
lilbeefor the full-screen terminal app. On first run you pick a chat model straight from the catalog, fit-checked against your hardware, then you index files, search, and chat without leaving the TUI. The Settings screen exposes every retrieval knob (search depth, distance threshold, reranker, chunking) so you can tune lilbee to your library shape. - Connect it to your agent over MCP. Any MCP-aware coding agent calls
lilbee_search/lilbee_addand gets back cited snippets it can quote. Agents can also fine-tune lilbee on the fly vialilbee_settings_set. Drop in the lilbee-mcp skill and the agent reads the full surface: every tool, every retrieval knob, and when to widen for prose vs narrow for code. See A reference for AI agents.
Retrieval defaults are sane, and every setting is tunable from env vars or config.toml, most of them from the TUI, MCP, and the HTTP API too; the settings reference has a column per surface. The CLI and HTTP API cover scripting and headless runs. See the usage guide.
Optional extras
These only matter for a pip or uv install: add the name in brackets, e.g. pip install --pre 'lilbee[engine,crawler,litellm]' (combine multiple, and --extra-index-url still works). The standalone binary and the Homebrew / AUR / Nix / Docker / Flatpak / Snap builds already include all four, which is why they need none of this. [engine] is the one that is not really optional; lilbee works fine without the other three. See the install commands in the usage guide for any uv install that has crawler in the extras list.
| Extra | What it adds |
|---|---|
[engine] | The bundled llama-server that runs your models. Published on lilbee.sh rather than PyPI, so it needs the --extra-index-url for your hardware; without it nothing can load a model. |
[crawler] | Index websites alongside your files: crawl a docs site or wiki to markdown, then search it offline. |
[litellm] | Bridge to hosted model providers for chat, vision, or embeddings while other roles stay local. The TUI flags when a hosted role is active. |
[graph] | Concept-graph search: extracts the ideas in your documents and uses how they relate to surface matches plain keyword search misses. No extra model calls. |
See the full guide on optional extras for configuration.
A reference for AI agents
Once configured, lilbee plugs into whatever agent you use, over MCP. Feed it your project's docs, your dependency source, your API docs, your design notes; the agent stops making up function names and instead reads the actual code, cites file and line, and says it doesn't know when the answer isn't in your library. The lilbee-mcp skill is the single entry point: drop it into .opencode/skills/ or .claude/skills/ and it documents every tool, the workflows the agent should follow, and points to drop-in AGENTS.md and worker-subagent starters under examples/agent-integration/. This works with cloud-model agents too; lilbee stays local, and only the queries and the returned chunks reach the model.
Your files, the search index, and the embeddings stay on your computer. The agent calls lilbee_search and gets back cited snippets with file and line. The agent reels above show this live: each pane reads and searches this repository through lilbee.
Supported models
lilbee's engine is llama.cpp, so lilbee runs what llama.cpp runs: any GGUF model built on one of the architectures below. The list comes from the bundled engine itself and grows with every engine update.
<details> <summary><b>All 152 supported model architectures. Click to expand.</b></summary>
afmoe | apertus | arcee | arctic |
arwkv7 | baichuan | bailingmoe | bailingmoe2 |
bailingmoe3 | bert | bitnet | bloom |
chameleon | chatglm | clip | codeshell |
cogvlm | cohere2 | cohere2moe | command-r |
dbrx | deci | deepseek | deepseek2 |
deepseek2-ocr | deepseek32 | deepseek4 | dflash |
dots1 | dots3note | dream | eagle3 |
ernie4_5 | ernie4_5-moe | eurobert | exaone |
exaone-moe | exaone4 | falcon | falcon-h1 |
gemma | gemma-embedding | gemma2 | gemma3 |
gemma3n | gemma4 | gemma4-assistant | glm-dsa |
glm4 | glm4moe | gpt-oss | gpt2 |
gptj | gptneox | granite | granite_swa |
granitehybrid | granitemoe | graniteswitch | grok |
grovemoe | hrm_text | hunyuan-dense | hunyuan-moe |
hunyuan_vl | hy_v3 | hy_v4 | internlm2 |
jais | jais2 | jamba | jina-bert-v2 |
jina-bert-v3 | kimi-k3 | kimi-linear | laguna |
lfm2 | lfm2moe | llada | llada-moe |
llama | llama-embed | llama4 | maincoder |
mamba | mamba2 | maple | mellum |
mimo2 | minicpm | minicpm3 | minimax-01 |
minimax-m2 | minimax-m3 | mistral3 | mistral4 |
modern-bert | mpt | muse-glimmer | nanbeige |
nemotron | nemotron_h | nemotron_h_moe | neo-bert |
nomic-bert | nomic-bert-moe | olmo | olmo2 |
olmoe | openelm | orion | paddleocr |
pangu-embedded | phi2 | phi3 | phimoe |
plamo | plamo2 | plamo3 | plm |
pockettts | qwen | qwen2 | qwen2moe |
qwen2vl | qwen3 | qwen35 | qwen35moe |
qwen3moe | qwen3next | qwen3tts | qwen3vl |
qwen3vlmoe | qwen4exp | refact | rnd1 |
rwkv6 | rwkv6qwen2 | rwkv7 | seed_oss |
smallthinker | smollm3 | spark2_5 | stablelm |
starcoder | starcoder2 | step35 | t5 |
t5encoder | talkie | wavtokenizer-dec | xverse |
</details>
One representative per family also runs the full pipeline end to end on real GPUs -- the models, method, and results are in docs/tested-models.md.
https://github.com/user-attachments/assets/993a63d4-9468-4a55-b9ed-e4b1ae1ed235
How lilbee compares
lilbee is built for consumer hardware and for people who don't want to babysit infrastructure. It isn't another model server you point an app at; it's a local search engine with the model runner built in. One install gives you the whole stack in a single executable:
- A search engine over your files, with answers that cite the source line, not just a model to chat with.
- A managed fleet, chat, embedding, vision, and reranking, spread across every GPU in the machine behind a load-balancing router, not one model loaded at a time.
- Everything bundled: model manager, search engine, web crawler, MCP server for coding agents (native opencode and hermes), HTTP server, TUI, and Python, in one file.
It sits between two worlds: the desktop runners that get a model chatting on your machine (Ollama, LM Studio), and vLLM, the server you stand up to push one model to a cluster of users. lilbee runs models to do retrieval over your files, and places that whole stack across the GPUs in the machine.
<details> <summary><b>Full comparison table: lilbee vs Ollama, LM Studio, and vLLM. Click to expand.</b></summary>
Full comparison table
| lilbee | [LM Studio](https://lmstudio.ai/) | [Ollama](https://ollama.com/) | [vLLM](https://github.com/vllm-project/vllm) | |
|---|---|---|---|---|
| **Primary focus** | local search, chat, and serving across your GPUs | desktop app to run and chat with models | local model runner with a growing ecosystem | high-throughput GPU serving |
| Runs local models | ✓ | ✓ | ✓ | ✓ |
| Search your own files, with citations | ✓ [full RAG pipeline](docs/architecture.md#search-pipeline), inline per-line citations | per-session doc attachment ([RAG, document-level citation](https://lmstudio.ai/docs/app/basics/rag)) | — | — |
| Chat, embedding, vision, rerank as one managed fleet | ✓ [all four, coordinated](docs/architecture.md#local-inference-engine) | chat, embed, vision (no rerank), [loaded individually](https://lmstudio.ai/docs/developer/core/server) | chat, embed, vision (no rerank), [loaded individually](https://docs.ollama.com/faq) | each supported, but [one model per server](https://docs.vllm.ai/en/stable/serving/openai_compatible_server/) |
| Multi-GPU model placement | ✓ [VRAM-aware tensor-split](docs/architecture.md#local-inference-engine) | ✓ GPU selection + [tensor parallelism (CUDA)](https://lmstudio.ai/changelog/lmstudio-v0.4.15) | ✓ [auto multi-GPU offload](https://docs.ollama.com/faq) | ✓ [tensor + pipeline parallel](https://docs.vllm.ai/en/latest/serving/parallelism_scaling.html) |
| Indexing spread across every GPU | ✓ [an embedding and OCR replica per GPU, load-balanced](docs/architecture.md#local-inference-engine) | — | — | — |
| Web crawler built in | ✓ [built in](#offline-copies-of-websites) | — | — | — |
| Long-term memory (opt-in) | ✓ [opt-in](docs/usage.md#memory) | — | — | — |
| Interfaces | [TUI, CLI, MCP, REST, Python](docs/architecture.md#interfaces), Obsidian GUI | [desktop GUI, lms CLI, Python + TS SDKs, REST API, MCP client](https://lmstudio.ai/docs) | [desktop GUI, CLI, REST API, Python/JS libs](https://docs.ollama.com/) | [API server](https://docs.vllm.ai/en/stable/serving/openai_compatible_server/) |
| Use your existing Ollama / LM Studio / cloud as a backend | ✓ [how](#already-running-ollama-or-lm-studio-keep-them) | — | — | — |
</details>
Of the four, lilbee is the only one built around retrieval. It places chat, embedding, vision, and reranking together across the GPUs in the machine, and spreads indexing across every card.
<details> <summary><b>Install size by platform: one file that undercuts the others while doing more. Click to expand.</b></summary>
lilbee 是一个开箱即用的本地数据与代码搜索引擎,旨在让你可以直接通过对话的方式与本地文档和代码库进行交互。它不仅是一个搜索工具,更是一个集成了检索与对话能力的智能助手,能够理解你的意图并基于本地上下文提供精准回答。
lilbee 提供全方位的交互体验,支持 TUI、CLI、MCP server、REST API 以及 Python library,通过简单的 `pip install` 即可完成部署,无需额外配置守护进程、推理服务器或向量数据库。其核心亮点在于回答会精准引用源代码行,点击即可跳转;同时支持索引包括 PDF、Office 文档、电子书及 150 多种语言的源代码在内的各类文本数据。
lilbee 采用 Standalone 模式,完全在本地运行,无需云端连接。硬件最低要求为 Apple Silicon Mac、2013 年以后的 64 位 Intel/AMD CPU 或 ARMv8 Linux 设备,配备 8 GB RAM 及 2 GB 磁盘空间。在 Linux 环境下,x86_64 版本需确保系统已安装 `libvulkan1`(如 Ubuntu 22.04+),否则在 Arch、Fedora 或 Alpine 等精简镜像中可能会因缺少 Vulkan loader 而导致 `lilbee self-check` 失败。
安装方式分为两条路径:1. Python 环境安装:使用 `pip` 或 `uv` 安装(支持 Python 3.11 至 3.14),这种方式体积更小,且能根据机器硬件自动选择最优的 CPU 执行路径,适合已有 Python 环境的开发者。2. 独立捆绑包安装:提供 Standalone binary、Homebrew、AUR、Nix 或 Docker 构建版本,无需安装任何依赖,开箱即用。此外,如果你正在使用支持 MCP 的 Agent,可以直接通过 Agent 完成自动化配置。
根据你的使用场景,lilbee 提供两种启动方式:如果你希望进行沉浸式交互,可以直接运行 `lilbee` 进入全屏终端应用(TUI),通过向导选择聊天与 Embedding 模型,并对文件进行索引;随后你可以在 TUI 中进行搜索与对话。TUI 内置了详尽的 Settings 界面,允许你精细调节搜索深度、距离阈值、Reranker 及分块(Chunking)策略,以适配不同规模的本地库。
对于通过 `pip` 或 `uv` 安装的用户,可以通过可选扩展进行增强,例如使用 `pip install --pre 'lilbee[crawler,litellm]'` 来添加爬虫或 LiteLLM 支持。而使用 Standalone binary 或 Docker 等构建版本时,所有功能已预装完毕。此外,若需通过 HTTP REST API(如 Obsidian 插件或自定义 GUI)调用 lilbee,建议通过 OS 启动器将其作为服务运行,以保持 HTTP server 处于热启动状态,避免冷启动延迟。
lilbee 正在积极集成 Opencode 支持,未来将实现对多种 GGUF 格式本地模型的 Tool-calling 支持。通过集成 `lilbee-mcp` skill,你可以将 lilbee 注册为 MCP server 并放入 `.opencode/skills/` 或 `.claude/skills/` 目录中。这样,任何支持 MCP 的编程 Agent(如 Claude)都能直接调用 lilbee 进行库搜索、模型切换及检索参数调优,实现智能化的本地知识检索工作流。
创新��MCP集成方案,结合本地搜索与AI对话。功能完整但生态成熟度有限,适合技术用户探索。
- 需要让 Claude / Cursor 操作本地工具的 AI 工程师
- 构建多智能体协作系统的 Agent 开发者
- 构建企业知识库 / RAG 检索应用的团队
- 需要从图片、PDF 提取文字的文档自动化场景
- 配置 MCP 服务器时建议使用 stdio 传输 + JSON-RPC,避免暴露公网
- 生产部署优先使用 Docker Compose 隔离依赖,并挂载 volume 持久化数据
- 本地部署优先选 GGUF 量化模型,节省显存并保持响应速度
- Agent 任务先做 dry-run 验证工具调用链,再开启自主执行
- API key 直接提交到 git 仓库(请用 .env 并加入 .gitignore)
- MCP 配置路径拼错或权限不足,重启 Claude Desktop 才生效
- 容器内无法访问宿主机 localhost — 使用 host.docker.internal
- 显存不足直接 OOM — 优先降低 context 或换更小的量化模型
- Python 依赖冲突:建议用 venv / uv 隔离环境
- Docker:lilbee 提供官方镜像,docker compose up 一键启动
- CLI:直接 npm install -g / pip install,命令行调用
- 本地部署:CPU 8GB 起,GPU 推荐 16GB+ 显存
- 云端托管:可放在 Vercel / Railway / Fly.io 等 PaaS 平台
⚡ 核心功能
- 通过标准 MCP 协议与 Claude、Cursor 等主流 AI 客户端深度集成
- 提供结构化工具调用接口,显著降低 AI 集成复杂度
- 支持 Claude Desktop 和 Claude Code 无缝接入,开箱即用
- 可与其他 MCP 工具组合叠加,构建完整 AI 工作站
- 轻量无侵入设计,不影响现有系统架构
- 需要让 Claude / Cursor 操作本地工具的 AI 工程师
- 构建多智能体协作系统的 Agent 开发者
- 构建企业知识库 / RAG 检索应用的团队
- 需要从图片、PDF 提取文字的文档自动化场景
- 配置 MCP 服务器时建议使用 stdio 传输 + JSON-RPC,避免暴露公网
- 生产部署优先使用 Docker Compose 隔离依赖,并挂载 volume 持久化数据
- 本地部署优先选 GGUF 量化模型,节省显存并保持响应速度
- Agent 任务先做 dry-run 验证工具调用链,再开启自主执行
- API key 直接提交到 git 仓库(请用 .env 并加入 .gitignore)
- MCP 配置路径拼错或权限不足,重启 Claude Desktop 才生效
- 容器内无法访问宿主机 localhost — 使用 host.docker.internal
- 显存不足直接 OOM — 优先降低 context 或换更小的量化模型
👥 适合人群
🎯 使用场景
- 在 Claude Desktop 对话中直接调用本地工具,实现 AI 与系统的深度联动
- 通过自然语言驱动复杂的多步骤自动化任务,代替繁琐手动操作
- 将多个 MCP 工具组合使用,构建个人专属 AI 工作站
⚖️ 优点与不足
- +标准化 MCP 协议,生态互联性强
- +与 Claude 官方生态无缝对接
- +即插即用,配置简单快捷
- −依赖 Claude 客户端,非 Claude 用户无法使用
- −MCP 协议仍在持续演进,接口可能变更
- −需要一定的配置步骤
该工具使用 NOASSERTION 协议,商用场景请仔细阅读协议条款,必要时咨询法律意见。
AI Skill Hub 为第三方内容聚合平台,本页面信息基于公开数据整理,不对工具功能和质量作任何法律背书。
建议在沙箱或测试环境中充分验证后,再部署至生产环境,并做好必要的安全评估。
📄 NOASSERTION — 请查阅原始协议条款了解具体使用限制。
🔗 相关工具推荐
❓ 常见问题 FAQ
经综合评估,lilbee MCP工具 在MCP工具赛道中表现稳健,质量良好。如果你已有明确的使用需求,可以直接上手体验;如果还在评估阶段,建议对比同类工具后再做决策。
| 原始名称 | lilbee |
| 原始描述 | 开源MCP工具:Terminal-first local search and AI chat over your documents, code, and crawled w。⭐18 · Python |
| Topics | 本地搜索文档对话网页爬虫向量嵌入终端工具 |
| GitHub | https://github.com/tobocop2/lilbee |
| License | NOASSERTION |
| 语言 | Python |
收录时间:2026-05-16 · 更新时间:2026-05-22 · License:NOASSERTION · AI Skill Hub 不对第三方内容的准确性作法律背书。